
Hi LGG community. I want to preface this with I am an engineer, i have learnt a lot about colour science, grading, etc, but in the end i understand maths, physics, and statistics. My field of research is in hardware accelerated stochastic rendering and I have used my relevant skill set to develop a full image-from-grain film simulation pipeline, fully simulating the grain itself, the chemical process in the emulsion process, the path traced light diffusion that causes halation, you name it I am simulating it.
I want this thread to serve as a jumping off point for potential further avenues of testing, development, and use case. I want to present to you the work if have done, the findings, and the results, as well as get some feedback from those of you with much more knowledge on how film is used (and abused) by film makers to achieve their vision as while the maths might be sound and match expectation, it is the feeling, the mood, the texture that film brings that artists love, and as an engineer I cannot fully ensure those needs are met.
I will break down the results in batches. Starting with the grain itself, and ending with the full look and feel of the pipeline. I will be using Kodak Vision3 500T as it's immense level of chemical engineering excellence provides a great deal of opportunity to demonstrate capabilities of stochastic rendering. I will also demonstrate the very new Kodak Verita 200D specifically for daylight 5200K scenes as these types of scenes really show what the 200D was made for vs the 3200K tungsten balanced 500T. I have Portra 800 and Gold 200 as well but those are generally used for Photography, I simulated them as "stress tests" of my engine essentially, to push the physics and see what happens.
This is by no means a completed project, it is a work in progress and i merely wish to share with you guys the state in which it is in, gather some feedback, and perhaps develop it towards an actual product if it is something people might want.
Rendering fundamentals:
Now to begin, a brief description of the engine and what stochastic rendering really is.
Most digital film emulation looks at a digital pixel and asks, "How do we make this look like film?" relying on static color mapping and 2D procedural noise or scanned overlays for grain.
My engine asks, "What physically happens when light energy hits this specific chemical medium?"
Stochastic rendering, at its core, is about probability and physical randomness. Real film isn't a uniform grid of pixels; it's a chaotic, three-dimensional suspension of silver halide crystals of varying sizes distributed through layers of gelatin. In my pipeline, the grain isn't an effect applied over the image at the end—it is the physical structure through which the image is actually formed. The engine generates these randomised crystal distributions using stochastic models.
Instead of simple RGB mapping, the engine calculates how scene-linear light interacts with this probabilistic structure. The simulated light energy scatters, and the crystals react and form dye clouds based on the physical sensitometry of the film stocks. The halation you see isn’t a radial blur node; it is the calculated byproduct of light energy physically bypassing the grain, hitting the anti-halation backing, and scattering back up into the emulsion layers. This distinction is important as RGB light has already undergone pre-processing by the digital camera the image was taken from, colour space transforms, etc. To properly simulate film's reaction, you have to try to being it back to what physical film would see.
Because the engine calculates the image from physical principles, the behaviors we associate with film—density-dependent grain structure, subtractive dye crosstalk, and the way saturated colours twist in the shoulder—aren't faked. They emerge naturally from the physics of the simulation.
I will start by showing you the raw stochastic grain structure before we move onto the dye layers.
pictured above is a zoomed in image of a dark area in a frame. The grain structures are formed from 16mm Vision3 500T with forced under exposure to ensure visible, crisp grain (dye bleed is forced off).
Moving on to the dye layers:
Once the physical grain sites are exposed, the engine models the actual chromogenic chemistry of the ECN-2 development process.
In real color negative stock, metallic silver is completely bleached away, leaving behind microscopic dye clouds formed by oxidized developer reacting with color couplers in the three primary emulsion layers:
Real photographic dyes are not mathematically pure optical filters:
Because the densities stack subtractively, the complex color interactions you see in real film—such as saturation compressing in the highlights as layers approach D_max, and hue shifts across high dynamic range ramps—emerge organically from the chemical curves rather than manual grading approximations.
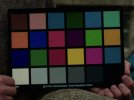
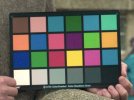
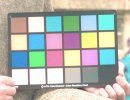
Below are 3 images taken from the Arri Alex 35 sample footage. One shows an underexposure of 3 stop, one a neutral exposure, and one an over exposure of 3 stops. This test demonstrates the dye depletion simulation showing how as exposure drops, the contrast flattens as the image falls into the toe, and conversely as exposure climbs, the dyes become "depleted", and each channel hits it's D_max at slightly different rates showing varying levels of de-saturation as they climb into their respective shoulders. Pictured from -3 up to +3 stops.
Note: grain is reduced for visibility.
Continuing on to "lighting" behavior:
This is a more complicated task, to balance remaining "true to life" and "looks good" for outdoor daylight scenes Auto normalising the midpoints provides a better image out of the box, but defeats the true look of 500T's cool blue cast in daylight scenes. So I use a toggle for auto balancing and not, with it off one has to either manually go set up a Chroma Adaption node, or if they WANT the cool blue cast, they can keep it.
Here i want to demonstrate the difference between 500T and Verita 200D. The 500T has a very wide open, roughly 14 stop, dynamic range, while the 200D is heavily constrained, opting to go for the nostalgic mid century look ,boosting contrast and crushing shadows. Another interesting effect of this is that on skin tones. I don't know quite enough to fully explain it, admittedly, but to the best of my knowledge as the skin tones near the toe due to exposure, they also get crushed down. I did not adjust the exposure between the 500T and 200D, i merely dropped it by 4 stops to as to (crudely) bring the dynamic range to about 13 max (Arri Alexa 35 has 17 stops in the sample footage i am using if i am not mistaken)
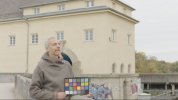
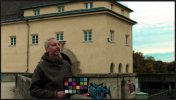
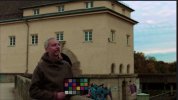
Above pictured is, in order, Direct Arri Raw to Rec.709 though CST, Vision3 500T, Verita 200D. The two film images are being auto balanced, which si the equivalent of putting the relevant filter over the lens when shooting. The compressed JPEGs might make it slightly difficult to see but the 500T is very willing to open up those midtones and stretch them into high brightness, while the 200D is compressing them down into the toe and crushing information while it goes. Every variable can be tweaked and meddled with so if the grading work is terrible i apologise, i very much suck at grading, the images are straight out of the engine. The 200D's skin tones can easily be fixed by slightly pushing exposure, over exposing the sky while retaining mid tone colours. The reason the corrective filters have to be applied by the maths is that to properly expose film two things need to be known, 1) the balance illuminant that Kodak or the relevant film manufacturer builds into their film chemistry, and 2) the Scene illuminant. Now if it were real life, the light hitting the film would have the real life correct scene illuminant, but because this was FIRST captured on a camera (in this isntance an ALEXA 35) and then converted to RGB with white balance already applied for 0.18 neutral grey, that scene information is lost entirely. So that begs the question, how do you properly expose the camera if you dont know the scene illuminant? You dont. I have to tell the engine what the illuminant is or let it auto balance. The way i am doing the maths for the RGB->Light Spectrum is losely based on the paper "A Low-Dimensional Function Space forEfficient Spectral Upsampling" with some custom modifications. Without being told, the engine has to auto white balance the neutral back and hence the images above are relatively similar.
Spatial Light Transport and Halation:
Now that we have established the stochastic grain structure, the dye chemistry, and the spectral response, the final major physical component to address is spatial light transport—specifically, what happens when high-intensity lighting interacts with the physical depth of the emulsion stack.
In many digital workflows, halation is approached as a localized spatial composite, typically by blurring the red channel around high-exposure areas. For this engine, I wanted to see what happens when halation is treated strictly as a physical light transport phenomenon calculated at the grain level.
When calculating the interaction of high-intensity light (like a bare practical bulb or a blown-out window) with the physical film plane, photons do not just stop at their exact X,Y coordinate. A percentage of high-energy photons penetrate completely through the top blue-sensitive and green-sensitive layers, pass through the red-sensitive layer, and strike the film base.
Cinema negative stocks like Vision3 500T and Verita 200D utilize a carbon Rem-Jet backing specifically to absorb this excess light. However, at extreme exposures, the backing cannot absorb 100% of the energy.
The engine simulates the path of these unabsorbed photons as they strike the backing and scatter back up into the film plane. Because the red-sensitive (cyan dye-forming) layer sits at the very bottom of the emulsion stack, directly against the base, it naturally absorbs the vast majority of this scattered bounce light.
By calculating this diffusion stochastically based on light transport rather than applying a spatial blur, two specific lighting characteristics emerge organically in the render:
If you would like me to demonstrate any specific phenomena, practices (pushing the film, bleach bypass, etc.) please let me know and i will reply ASAP.
I want this thread to serve as a jumping off point for potential further avenues of testing, development, and use case. I want to present to you the work if have done, the findings, and the results, as well as get some feedback from those of you with much more knowledge on how film is used (and abused) by film makers to achieve their vision as while the maths might be sound and match expectation, it is the feeling, the mood, the texture that film brings that artists love, and as an engineer I cannot fully ensure those needs are met.
I will break down the results in batches. Starting with the grain itself, and ending with the full look and feel of the pipeline. I will be using Kodak Vision3 500T as it's immense level of chemical engineering excellence provides a great deal of opportunity to demonstrate capabilities of stochastic rendering. I will also demonstrate the very new Kodak Verita 200D specifically for daylight 5200K scenes as these types of scenes really show what the 200D was made for vs the 3200K tungsten balanced 500T. I have Portra 800 and Gold 200 as well but those are generally used for Photography, I simulated them as "stress tests" of my engine essentially, to push the physics and see what happens.
This is by no means a completed project, it is a work in progress and i merely wish to share with you guys the state in which it is in, gather some feedback, and perhaps develop it towards an actual product if it is something people might want.
Rendering fundamentals:
Now to begin, a brief description of the engine and what stochastic rendering really is.
Most digital film emulation looks at a digital pixel and asks, "How do we make this look like film?" relying on static color mapping and 2D procedural noise or scanned overlays for grain.
My engine asks, "What physically happens when light energy hits this specific chemical medium?"
Stochastic rendering, at its core, is about probability and physical randomness. Real film isn't a uniform grid of pixels; it's a chaotic, three-dimensional suspension of silver halide crystals of varying sizes distributed through layers of gelatin. In my pipeline, the grain isn't an effect applied over the image at the end—it is the physical structure through which the image is actually formed. The engine generates these randomised crystal distributions using stochastic models.
Instead of simple RGB mapping, the engine calculates how scene-linear light interacts with this probabilistic structure. The simulated light energy scatters, and the crystals react and form dye clouds based on the physical sensitometry of the film stocks. The halation you see isn’t a radial blur node; it is the calculated byproduct of light energy physically bypassing the grain, hitting the anti-halation backing, and scattering back up into the emulsion layers. This distinction is important as RGB light has already undergone pre-processing by the digital camera the image was taken from, colour space transforms, etc. To properly simulate film's reaction, you have to try to being it back to what physical film would see.
Because the engine calculates the image from physical principles, the behaviors we associate with film—density-dependent grain structure, subtractive dye crosstalk, and the way saturated colours twist in the shoulder—aren't faked. They emerge naturally from the physics of the simulation.
I will start by showing you the raw stochastic grain structure before we move onto the dye layers.
pictured above is a zoomed in image of a dark area in a frame. The grain structures are formed from 16mm Vision3 500T with forced under exposure to ensure visible, crisp grain (dye bleed is forced off).
Moving on to the dye layers:
Once the physical grain sites are exposed, the engine models the actual chromogenic chemistry of the ECN-2 development process.
In real color negative stock, metallic silver is completely bleached away, leaving behind microscopic dye clouds formed by oxidized developer reacting with color couplers in the three primary emulsion layers:
- Cyan-forming layer (Red-sensitive)
- Magenta-forming layer (Green-sensitive)
- Yellow-forming layer (Blue-sensitive)
Subtractive Density & Unwanted Absorptions
The important difference between additive digital RGB and physical film comes down to how real-world dyes transmit light.Real photographic dyes are not mathematically pure optical filters:
- Cyan dyes have secondary unwanted absorptions in the green and blue wavelengths.
- Magenta dyes have minor secondary absorptions in the blue wavelengths.
Because the densities stack subtractively, the complex color interactions you see in real film—such as saturation compressing in the highlights as layers approach D_max, and hue shifts across high dynamic range ramps—emerge organically from the chemical curves rather than manual grading approximations.
Below are 3 images taken from the Arri Alex 35 sample footage. One shows an underexposure of 3 stop, one a neutral exposure, and one an over exposure of 3 stops. This test demonstrates the dye depletion simulation showing how as exposure drops, the contrast flattens as the image falls into the toe, and conversely as exposure climbs, the dyes become "depleted", and each channel hits it's D_max at slightly different rates showing varying levels of de-saturation as they climb into their respective shoulders. Pictured from -3 up to +3 stops.
Note: grain is reduced for visibility.
Continuing on to "lighting" behavior:
This is a more complicated task, to balance remaining "true to life" and "looks good" for outdoor daylight scenes Auto normalising the midpoints provides a better image out of the box, but defeats the true look of 500T's cool blue cast in daylight scenes. So I use a toggle for auto balancing and not, with it off one has to either manually go set up a Chroma Adaption node, or if they WANT the cool blue cast, they can keep it.
Here i want to demonstrate the difference between 500T and Verita 200D. The 500T has a very wide open, roughly 14 stop, dynamic range, while the 200D is heavily constrained, opting to go for the nostalgic mid century look ,boosting contrast and crushing shadows. Another interesting effect of this is that on skin tones. I don't know quite enough to fully explain it, admittedly, but to the best of my knowledge as the skin tones near the toe due to exposure, they also get crushed down. I did not adjust the exposure between the 500T and 200D, i merely dropped it by 4 stops to as to (crudely) bring the dynamic range to about 13 max (Arri Alexa 35 has 17 stops in the sample footage i am using if i am not mistaken)
Above pictured is, in order, Direct Arri Raw to Rec.709 though CST, Vision3 500T, Verita 200D. The two film images are being auto balanced, which si the equivalent of putting the relevant filter over the lens when shooting. The compressed JPEGs might make it slightly difficult to see but the 500T is very willing to open up those midtones and stretch them into high brightness, while the 200D is compressing them down into the toe and crushing information while it goes. Every variable can be tweaked and meddled with so if the grading work is terrible i apologise, i very much suck at grading, the images are straight out of the engine. The 200D's skin tones can easily be fixed by slightly pushing exposure, over exposing the sky while retaining mid tone colours. The reason the corrective filters have to be applied by the maths is that to properly expose film two things need to be known, 1) the balance illuminant that Kodak or the relevant film manufacturer builds into their film chemistry, and 2) the Scene illuminant. Now if it were real life, the light hitting the film would have the real life correct scene illuminant, but because this was FIRST captured on a camera (in this isntance an ALEXA 35) and then converted to RGB with white balance already applied for 0.18 neutral grey, that scene information is lost entirely. So that begs the question, how do you properly expose the camera if you dont know the scene illuminant? You dont. I have to tell the engine what the illuminant is or let it auto balance. The way i am doing the maths for the RGB->Light Spectrum is losely based on the paper "A Low-Dimensional Function Space forEfficient Spectral Upsampling" with some custom modifications. Without being told, the engine has to auto white balance the neutral back and hence the images above are relatively similar.
Spatial Light Transport and Halation:
Now that we have established the stochastic grain structure, the dye chemistry, and the spectral response, the final major physical component to address is spatial light transport—specifically, what happens when high-intensity lighting interacts with the physical depth of the emulsion stack.
In many digital workflows, halation is approached as a localized spatial composite, typically by blurring the red channel around high-exposure areas. For this engine, I wanted to see what happens when halation is treated strictly as a physical light transport phenomenon calculated at the grain level.
When calculating the interaction of high-intensity light (like a bare practical bulb or a blown-out window) with the physical film plane, photons do not just stop at their exact X,Y coordinate. A percentage of high-energy photons penetrate completely through the top blue-sensitive and green-sensitive layers, pass through the red-sensitive layer, and strike the film base.
Cinema negative stocks like Vision3 500T and Verita 200D utilize a carbon Rem-Jet backing specifically to absorb this excess light. However, at extreme exposures, the backing cannot absorb 100% of the energy.
The engine simulates the path of these unabsorbed photons as they strike the backing and scatter back up into the film plane. Because the red-sensitive (cyan dye-forming) layer sits at the very bottom of the emulsion stack, directly against the base, it naturally absorbs the vast majority of this scattered bounce light.
By calculating this diffusion stochastically based on light transport rather than applying a spatial blur, two specific lighting characteristics emerge organically in the render:
- Energy-Dependent Propagation: The halation does not have a fixed radius or a linear fall-off. The distance the scatter propagates across the film plane is tied directly to the calculated physical energy of the light source. A +6 EV highlight will cause a physically wider photon scatter than a +3 EV highlight, dynamically wrapping around high-contrast edges.
- Micro-Contrast Decay: Physical bounce light doesn't just create a red glow; it scatters into adjacent, otherwise unexposed silver halide crystals. This eats into local micro-contrast and organically lifts the density of the shadows immediately surrounding a bright light source, accurately reproducing the optical "bloom" that alters edge contrast in physical photography.
If you would like me to demonstrate any specific phenomena, practices (pushing the film, bleach bypass, etc.) please let me know and i will reply ASAP.


